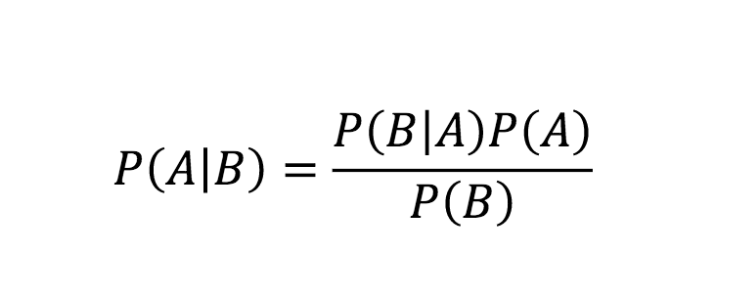11 key concepts of Machine Learning.

— Supervised Learning Edition —

🧵👇

😜

Before starting, remember that, if you follow me, one of your enemies will be immediately destroyed (and you'll get to read more of these threads, of course.)

And if you don't follow me, well, you just hurt my feelings.

😜
1. Labels

(Also referred to as "y")

The label is the piece of information that we are predicting.

For example:

- the animal that's shown in a picture
- the price of a house
- whether a message is spam or not

👇
2. Features

(Also referred to as "x")

These are the input variables to our problem. We use these features to predict the "label."

For example:

- pixels of a picture
- number of bedrooms of a house
- square footage of a house

👇
3. Samples

(This is also known as "examples.")

A sample is a particular instance of data (features or "x.") It could be "labeled" or "unlabeled."

👇
4. Labeled sample

Labeled samples are used to train and validate the model. These are usually represented as (x, y), where "x" is a vector containing all the features, and "y" is the corresponding label.

For example, a labeled sample could be:

([3, 2, 1500], 350000)
5. Unlabeled sample

Unlabeled samples contain features, but they don't contain the label: (x, ?)

We usually use a model to predict the labels of unlabeled samples.

👇
6. Model

A model defines the relationship between features and the label.

You can think of a model as a set of rules that, given certain features, determines the corresponding label.

For example, given the # of bedrooms, bathrooms, and square footage, we get the price.

👇
7. Training

Training is a process that builds a model.

We show the model labeled samples during training and allow the model to gradually learn the relationships between features and the label.

👇
8. Validation

Validation is the process that lets us know whether a model is any good.

Usually, we run a set of (unseen) labeled samples through a model to ensure that it can predict the labels.

👇
9. Inference

Inference is the process of applying a trained model to unlabeled samples to obtain the corresponding labels.

In other words, "inference" is the process of making predictions using a model.

👇
10. Regression

A regression model predicts continuous values, for example:

- the value of a house
- the price of a stock
- tomorrow's temperature

👇
11. Classification

A classification model predicts discrete values, for example:

- the picture is showing a dog or a cat
- the message is spam or not
- the forecast is sunny or overcast

More from Santiago

You gotta think about this one carefully!

Imagine you go to the doctor and get tested for a rare disease (only 1 in 10,000 people get it.)

The test is 99% effective in detecting both sick and healthy people.

Your test comes back positive.

Are you really sick? Explain below 👇

The most complete answer from every reply so far is from Dr. Lena. Thanks for taking the time and going through


You can get the answer using Bayes' theorem, but let's try to come up with it in a different —maybe more intuitive— way.

👇


Here is what we know:

- Out of 10,000 people, 1 is sick
- Out of 100 sick people, 99 test positive
- Out of 100 healthy people, 99 test negative

Assuming 1 million people take the test (including you):

- 100 of them are sick
- 999,900 of them are healthy

👇

Let's now test both groups, starting with the 100 people sick:

▫️ 99 of them will be diagnosed (correctly) as sick (99%)

▫️ 1 of them is going to be diagnosed (incorrectly) as healthy (1%)

👇

More from Machine learning

This is a Twitter series on #FoundationsOfML.

❓ Today, I want to start discussing the different types of Machine Learning flavors we can find.

This is a very high-level overview. In later threads, we'll dive deeper into each paradigm... 👇🧵

Last time we talked about how Machine Learning works.

Basically, it's about having some source of experience E for solving a given task T, that allows us to find a program P which is (hopefully) optimal w.r.t. some metric


According to the nature of that experience, we can define different formulations, or flavors, of the learning process.

A useful distinction is whether we have an explicit goal or desired output, which gives rise to the definitions of 1️⃣ Supervised and 2️⃣ Unsupervised Learning 👇

1️⃣ Supervised Learning

In this formulation, the experience E is a collection of input/output pairs, and the task T is defined as a function that produces the right output for any given input.

👉 The underlying assumption is that there is some correlation (or, in general, a computable relation) between the structure of an input and its corresponding output and that it is possible to infer that function or mapping from a sufficiently large number of examples.

You May Also Like

These 10 threads will teach you more than reading 100 books

Five billionaires share their top lessons on startups, life and entrepreneurship (1/10)


10 competitive advantages that will trump talent (2/10)


Some harsh truths you probably don’t want to hear (3/10)


10 significant lies you’re told about the world (4/10)