This is Karma. Karma is not a machine learning classifier πŸ•β€πŸ¦Ί

Karma is a real dog trained to detect drugs. However, he would fail the simplest tests we apply in ML...

Let me take you through this story from the eyes of an ML engineer.

https://t.co/WAXRUlTvSI

Thread 🧡

Story TLDR πŸ”–

The story is about police dogs trained to sniff drugs. The problem is that the dogs often signal drugs even if there are none. Then innocent people land in jail for days.

The cops even joke about the β€œprobable cause on four legs”.

Let's see why is that πŸ‘‡
1. Sampling Bias 🀏

Drugs were found in 64% of the cars Karma identified, which was praised by the police as very good. In the end, most people don't carry drugs in their cars, so 64% seems solid.

There was a sampling problem though... πŸ‘‡
The cars were not sampled at random! The police only did the sniff test if there was a serious suspicion that something is wrong.

The chance there are drugs in the car is much higher in this case!
2. Evaluation Metrics πŸ”

The police referred to a 2014 study from Poland measuring the efficacy of sniffer dogs. The problem was that every test actually contained drugs!

This means there was no chance to measure false positives from the dogs! Only recall, not precision πŸ€¦β€β™‚οΈ
3. Leaking Training Data 🚰

Another study found that the dogs learned to recognize the emotions of their handlers during tests. They felt that their human wanted them to find drugs in the specific test scenario, so they did.

The trainer leaked the ground truth during testing.
4. Overfitting ➿

Similar to the one above, in many cases, the dog saw that their handler wanted to find drugs in a car during a traffic stop. So it would raise an alarm.

The dog was rewarded before the car was actually searched! It found an easy signal giving it a reward.
Summary 🏁

It is fascinating how many problems there are with the sniffer dogs that are well known to machine learning engineers (and of course mathematicians). Some of them are even common sense...

Avoid these problems not only when training your model, but also in life πŸ˜ƒ
If you liked this thread and want to read more about self-driving cars and machine learning follow me @haltakov!

More from Vladimir Haltakov

Let's talk about a common problem in ML - imbalanced data βš–οΈ

Imagine we want to detect all pixels belonging to a traffic light from a self-driving car's camera. We train a model with 99.88% performance. Pretty cool, right?

Actually, this model is useless ❌

Let me explain πŸ‘‡


The problem is the data is severely imbalanced - the ratio between traffic light pixels and background pixels is 800:1.

If we don't take any measures, our model will learn to classify each pixel as background giving us 99.88% accuracy. But it's useless!

What can we do? πŸ‘‡

Let me tell you about 3 ways of dealing with imbalanced data:

β–ͺ️ Choose the right evaluation metric
β–ͺ️ Undersampling your dataset
β–ͺ️ Oversampling your dataset
β–ͺ️ Adapting the loss

Let's dive in πŸ‘‡

1️⃣ Evaluation metrics

Looking at the overall accuracy is a very bad idea when dealing with imbalanced data. There are other measures that are much better suited:
β–ͺ️ Precision
β–ͺ️ Recall
β–ͺ️ F1 score

I wrote a whole thread on


2️⃣ Undersampling

The idea is to throw away samples of the overrepresented classes.

One way to do this is to randomly throw away samples. However, ideally, we want to make sure we are only throwing away samples that look similar.

Here is a strategy to achieve that πŸ‘‡
Machine Learning Paper Reviews πŸ”ŽπŸ“œ

Check out this thread for short reviews of some interesting Machine Learning and Computer Vision papers. I explain the basic ideas and main takeaways of each paper in a Twitter thread.

πŸ‘‡ I'm adding new reviews all the time! πŸ‘‡

AlexNet - the paper that started the deep learning revolution in Computer Vision!


DenseNet - reducing the size and complexity of CNNs by adding dense connections between layers.


Playing for data - generating synthetic GT from a video game (GTA V) and using it to improving semantic segmentation models.


Transformers for image recognition - a new paper with the potential to replace convolutions with a transformer.
Machine Learning in the Real World 🧠 πŸ€–

ML for real-world applications is much more than designing fancy networks and fine-tuning parameters.

In fact, you will spend most of your time curating a good dataset.

Let's go through the process together πŸ‘‡

#RepostFriday


Collect Data πŸ’½

We need to represent the real world as accurately as possible. If some situations are underrepresented we are introducing Sampling Bias.

Sampling Bias is nasty because we'll have high test accuracy, but our model will perform badly when deployed.

πŸ‘‡

Traffic Lights 🚦

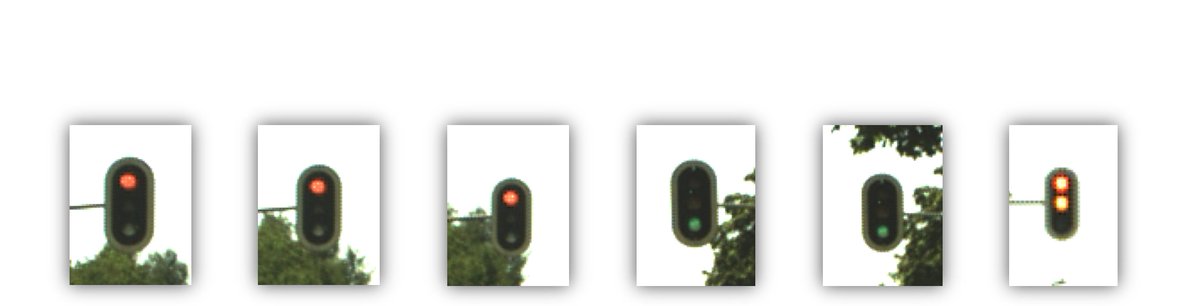
Let's build a model to recognize traffic lights for a self-driving car. We need to collect data for different:

β–ͺ️ Lighting conditions
β–ͺ️ Weather conditions
β–ͺ️ Distances and viewpoints
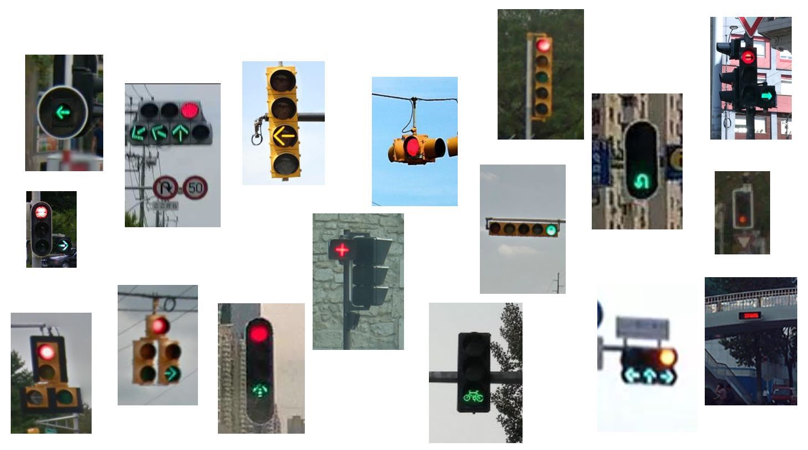
β–ͺ️ Strange variants

And if we sample only 🚦 we won't detect πŸš₯ πŸ€·β€β™‚οΈ

πŸ‘‡


Data Cleaning 🧹

Now we need to clean all corrupted and irrelevant samples. We need to remove:

β–ͺ️ Overexposed or underexposed images
β–ͺ️ Images in irrelevant situations
β–ͺ️ Faulty images

Leaving them in the dataset will hurt our model's performance!

πŸ‘‡


Preprocess Data βš™οΈ

Most ML models like their data nicely normalized and properly scaled. Bad normalization can also lead to worse performance (I have a nice story for another time...)

β–ͺ️ Crop and resize all images
β–ͺ️ Normalize all values (usually 0 mean and 1 std. dev.)

πŸ‘‡

More from All

You May Also Like

Trading view scanner process -

1 - open trading view in your browser and select stock scanner in left corner down side .

2 - touch the percentage% gain change ( and u can see higest gainer of today)


3. Then, start with 6% gainer to 20% gainer and look charts of everyone in daily Timeframe . (For fno selection u can choose 1% to 4% )

4. Then manually select the stocks which are going to give all time high BO or 52 high BO or already given.

5. U can also select those stocks which are going to give range breakout or already given range BO

6 . If in 15 min chartπŸ“Š any stock sustaing near BO zone or after BO then select it on your watchlist

7 . Now next day if any stock show momentum u can take trade in it with RM

This looks very easy & simple but,

U will amazed to see it's result if you follow proper risk management.

I did 4x my capital by trading in only momentum stocks.

I will keep sharing such learning thread 🧡 for you πŸ™πŸ’žπŸ™

Keep learning / keep sharing πŸ™
@AdityaTodmal